Pretrain
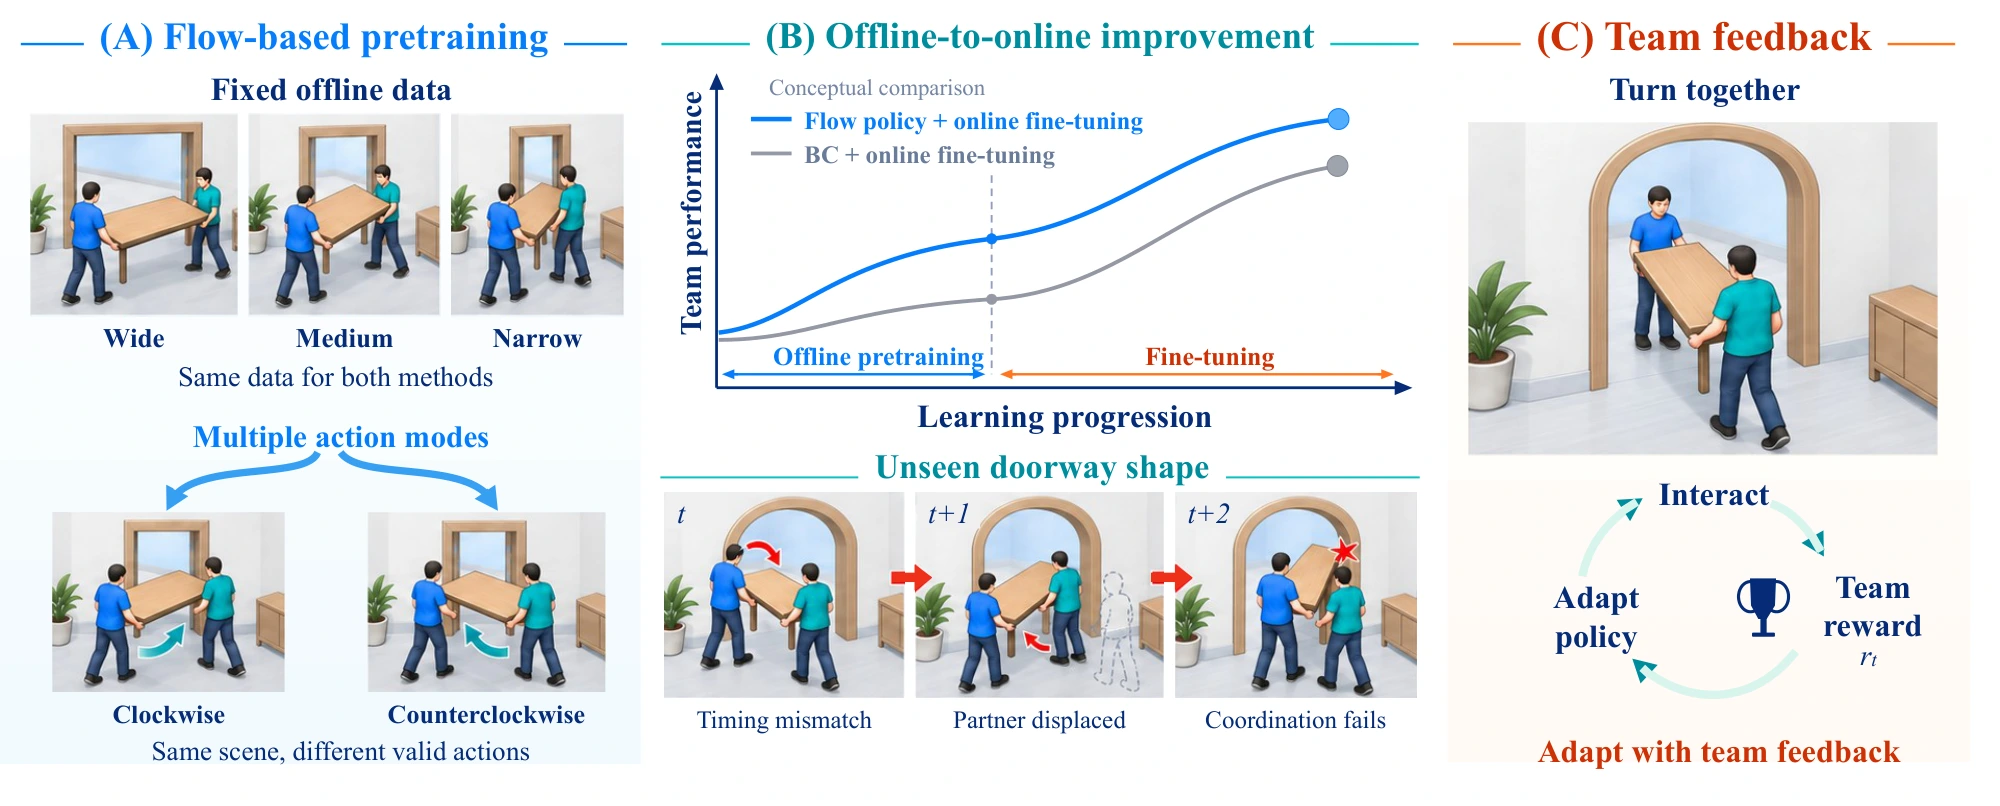
Learn cooperative behavior from offline data using flow matching and student distillation.
LEARN OFFLINE. IMPROVE THROUGH INTERACTION.
MA-FPPO builds on offline flow pretraining and uses online interaction to improve cooperative behavior.
1 Sun Yat-sen University · 2 National University of Singapore
01 / Overview
Offline flow policies learn coordinated behavior from recorded trajectories. Online fine-tuning lets agents adapt this behavior through new environment interactions and shared team feedback.
02 / Method
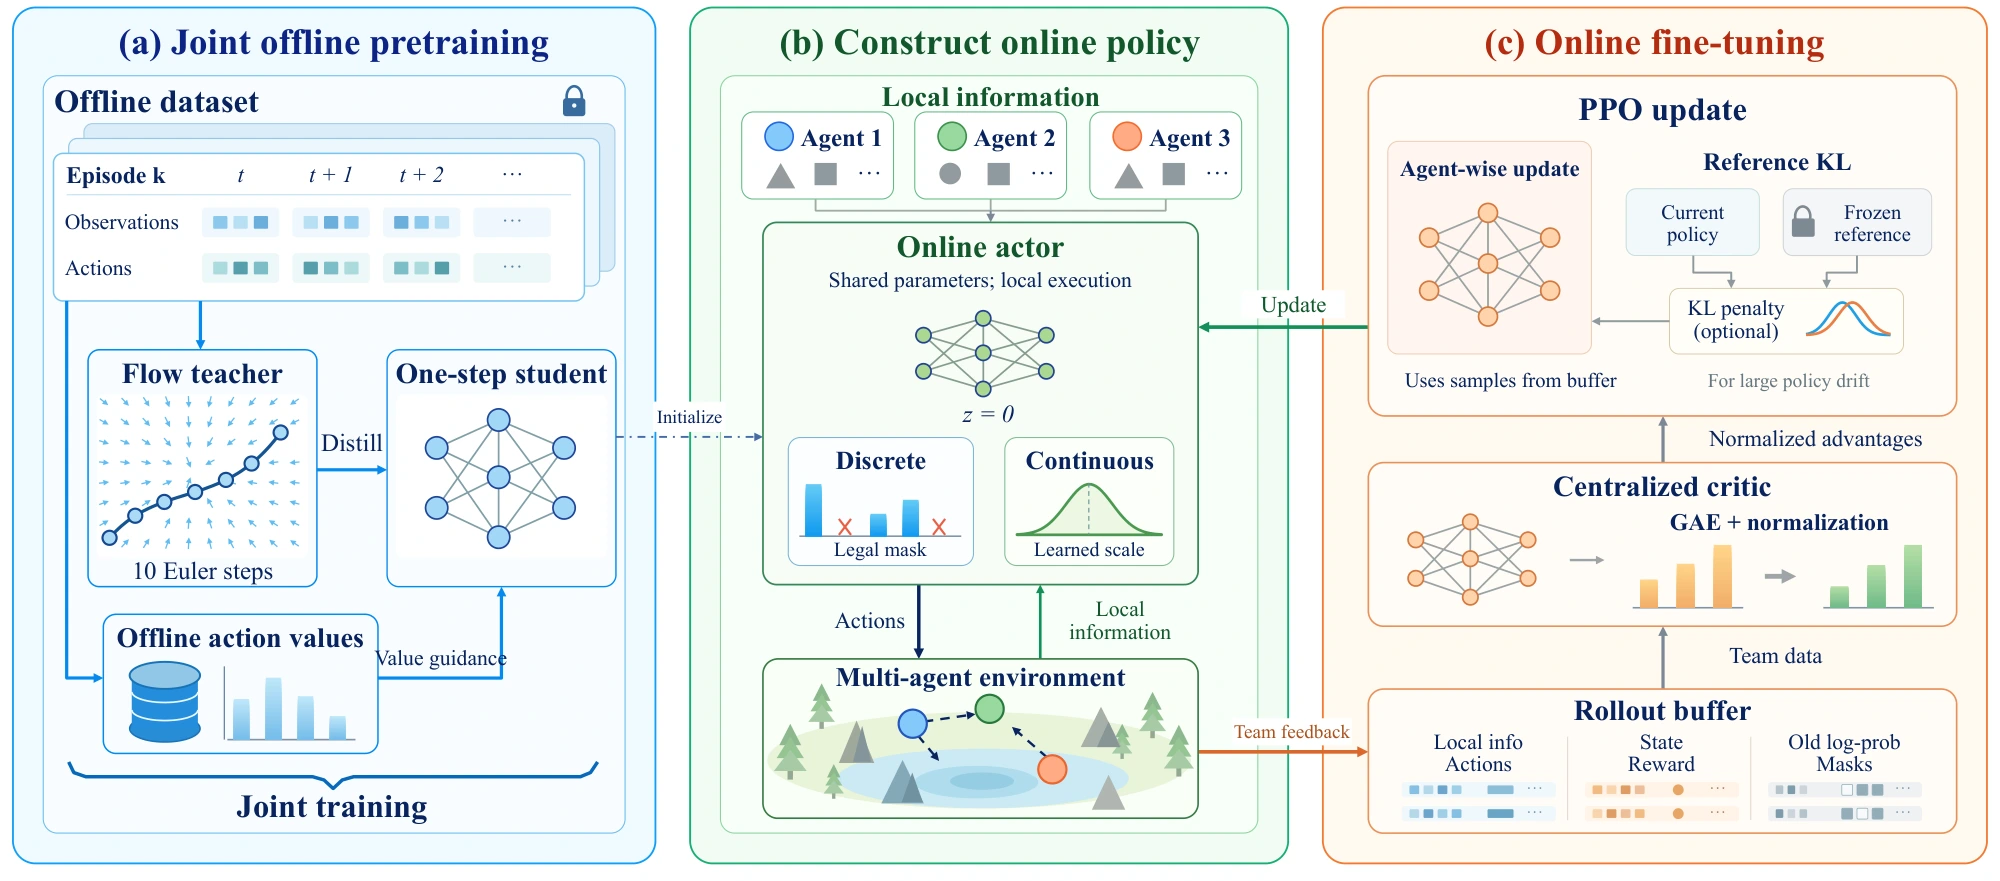
Learn cooperative behavior from offline data using flow matching and student distillation.
For continuous actions, use the student output at a fixed latent as the Gaussian mean and learn the standard deviation. For discrete actions, use a masked categorical policy.
Use a centralized critic and shared team advantages to update the student. The action mean changes as the student learns.
03 / Results
04 / Policy rollouts
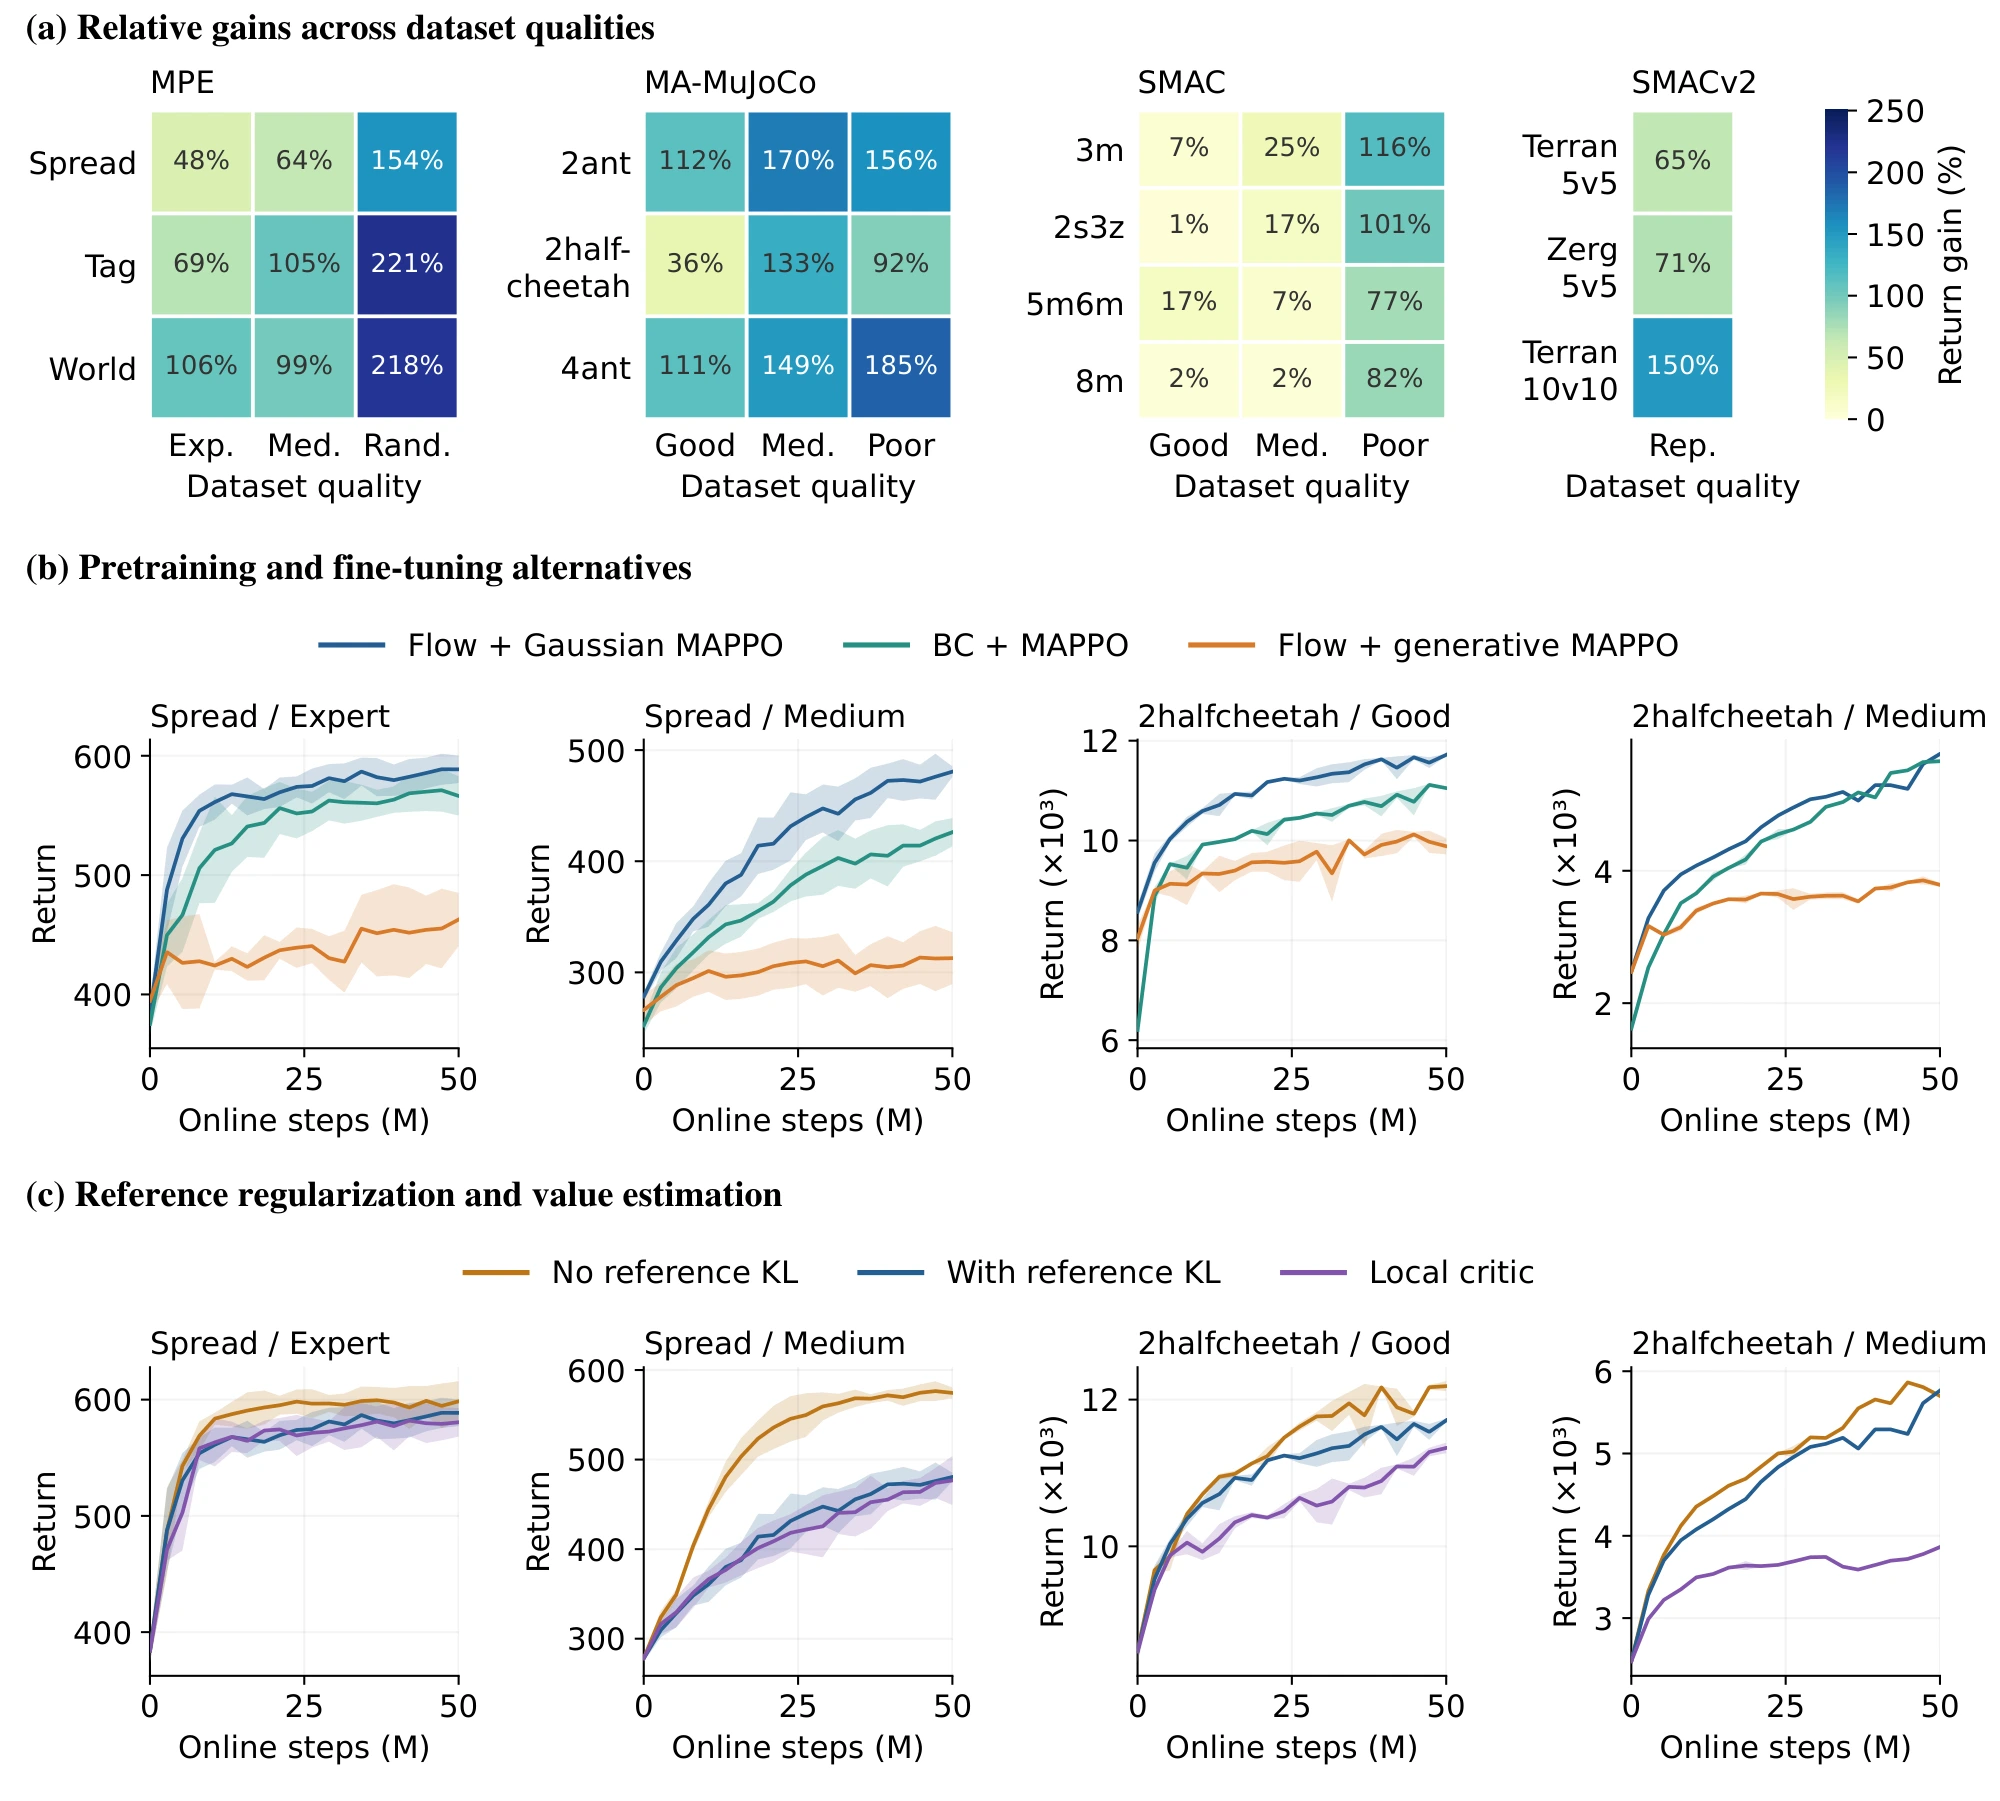
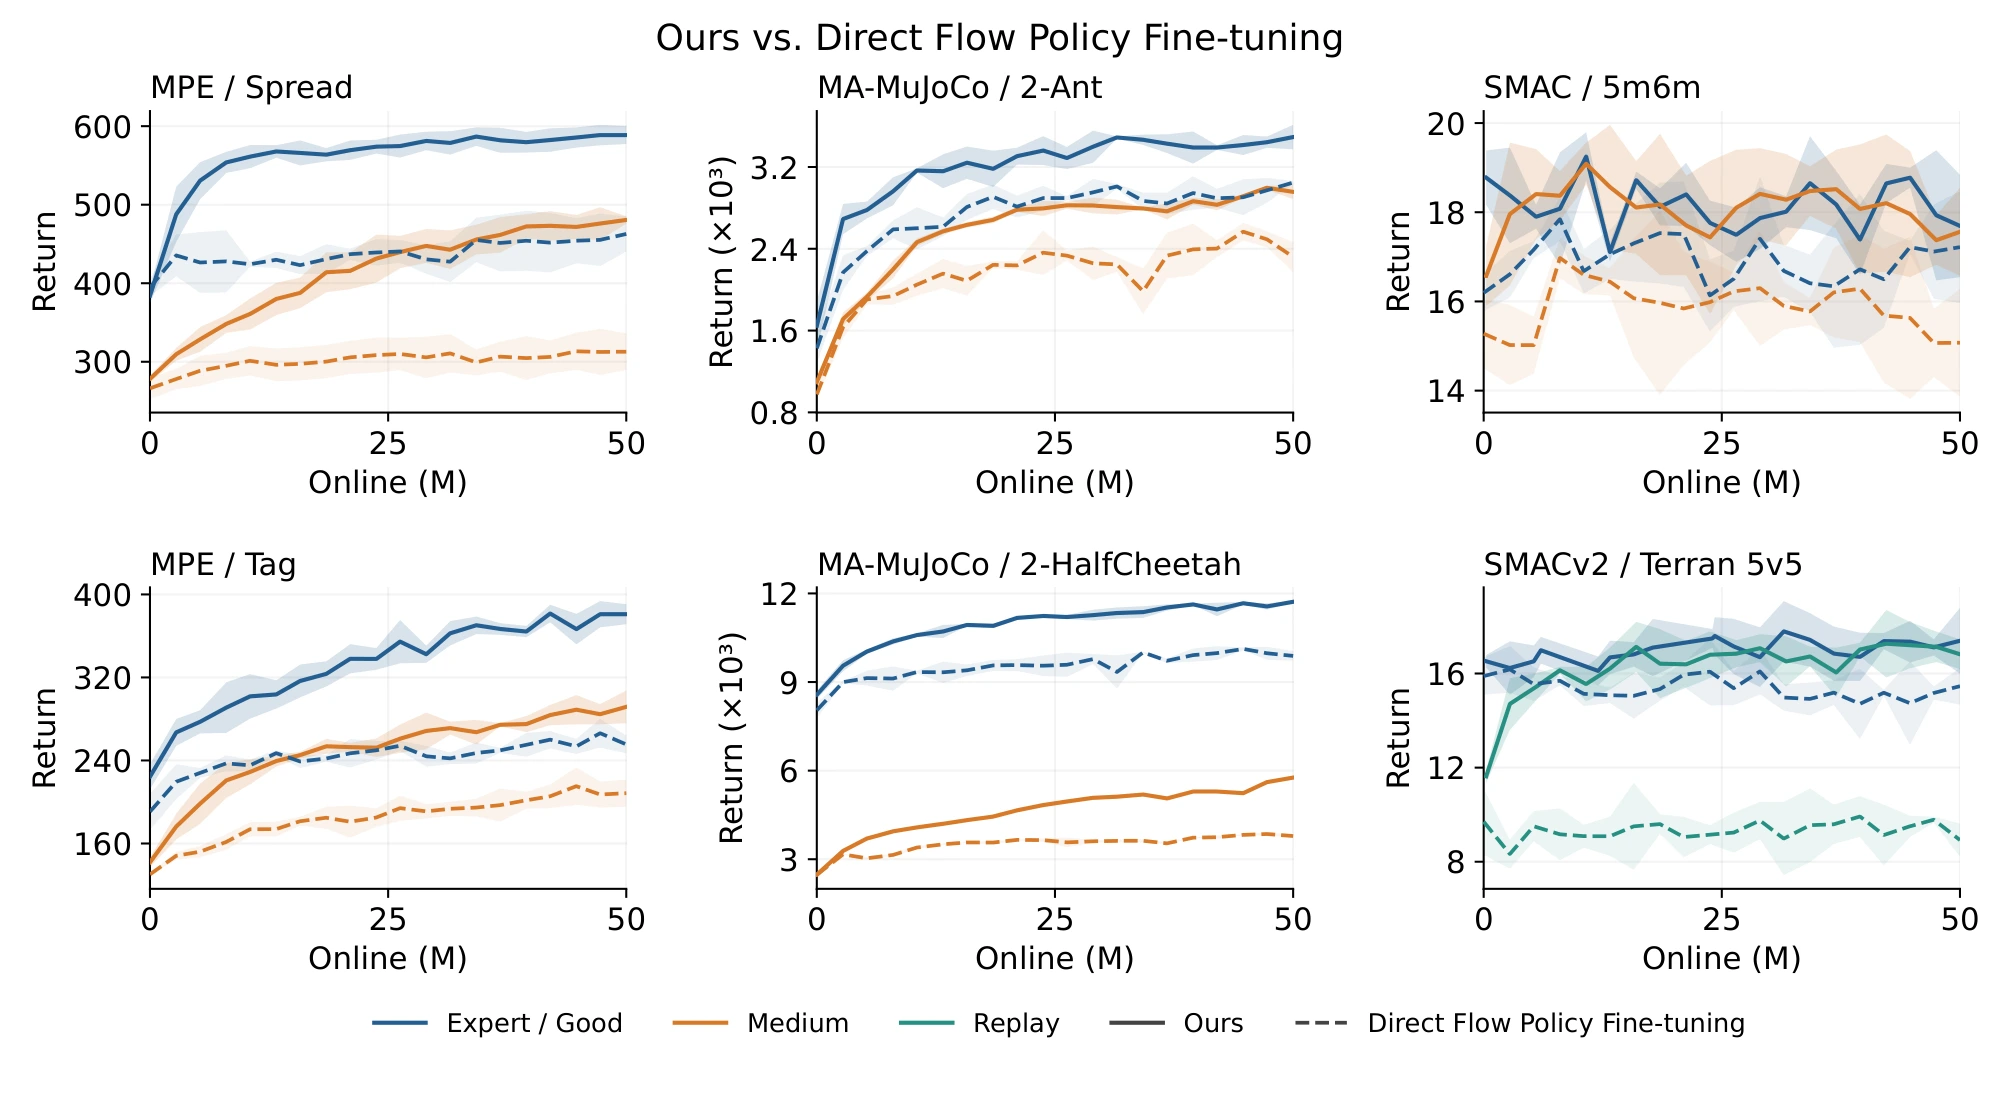
Recorded policy executions from the paper. These are individual trajectories; quantitative comparisons are reported in the manuscript.
05 / Resources
Code repository (public). The code includes 49 main-experiment recipes. 98 main-experiment checkpoints are available on Hugging Face, including pretrained and online fine-tuned models.
Shared CoFlow datasets currently provide MPE Tag and World. Additional benchmarks require the upstream sources and conversion instructions in the release’s DATA.md.
@misc{zou2026mafppo,
  title={MA-FPPO: Multi-Agent Flow-Pretrained Policy Optimization},
  author={Zou, Guowei and Chen, Haonan and Wang, Haitao and Zhang, Beiwen and Yan, Na and Wu, Hejun},
  year={2026},
  eprint={2609.32594},
  archivePrefix={arXiv},
  primaryClass={cs.AI},
  url={https://arxiv.org/abs/2609.32594}
}